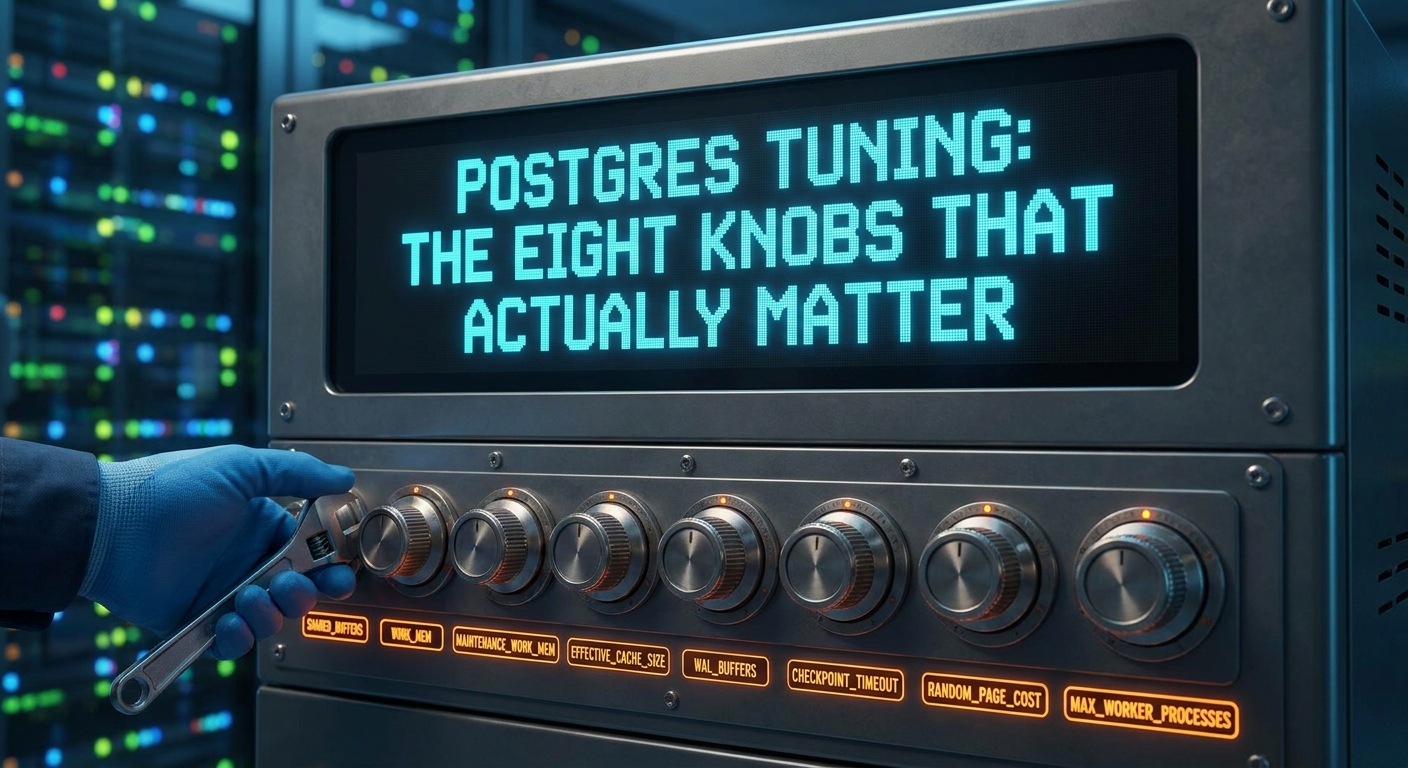
Postgres ships with defaults tuned to run on a 256MB machine from 2005. If you've deployed it anywhere built this decade, you're leaving performance on the floor. Here are the eight settings I change on every new instance, in the order I change them.
1. shared_buffers
The most important setting. This is Postgres's own memory cache for data pages. More is (almost always) better.
# Default: 128MB — laughably small
shared_buffers = 4GB   # 25% of RAM is the classic starting point
On Linux, Postgres also benefits from the OS page cache — so the total effective cache is shared_buffers + whatever the OS hasn't evicted. Setting shared_buffers to 40% or higher can starve the OS cache and hurt performance. 25% is a good starting default.
2. work_mem
Memory allocated per sort/hash operation, per query, per operation. A query with three hash joins can use 3 × work_mem. Set this too high and you'll OOM under concurrent load.
work_mem = 64MB # Default: 4MB — causes disk sorts on anything real
The right number depends on your concurrency. For a server with 32GB RAM and 100 max connections, work_mem = 64MB means you could theoretically allocate 6.4GB to sort operations alone. Size accordingly.
3. effective_cache_size
This doesn't allocate anything — it's a hint to the planner about how much memory is available for caching. A higher value makes the planner more willing to use index scans (which benefit from cache) over seq scans.
effective_cache_size = 12GB # Default: 4GB. Set to ~75% of total RAM.
4. maintenance_work_mem
Used for VACUUM, CREATE INDEX, and ALTER TABLE. Set higher than work_mem — maintenance tasks aren't concurrent with each other the way queries are.
maintenance_work_mem = 1GB # Default: 64MB
A larger maintenance_work_mem directly speeds up index creation. On large tables this can cut CREATE INDEX CONCURRENTLY time by 4–5×.
5. wal_buffers
Write-ahead log buffer size. The default was set conservatively and is almost always too small for write-heavy workloads.
wal_buffers = 64MB # Default: -1 (auto = 3% of shared_buffers, often ~4MB)
6. checkpoint_completion_target
Postgres writes dirty pages to disk at each checkpoint. This setting controls how much of the checkpoint interval to spread that I/O across. The default (0.5) concentrates the I/O in the first half — set it higher to smooth out write spikes.
checkpoint_completion_target = 0.9 # Default: 0.5
7. max_wal_size
Controls how much WAL can accumulate before forcing a checkpoint. Too small = frequent checkpoints = I/O spikes. Too large = longer crash recovery.
max_wal_size = 4GB # Default: 1GB
8. random_page_cost
The planner's assumed cost ratio of a random page read vs a sequential page read. The default (4.0) was tuned for spinning disks. On SSDs and NVMe, the ratio is close to 1.0.
random_page_cost = 1.1 # Default: 4.0 — on SSD/NVMe instances
Getting this wrong is one of the most common causes of Postgres choosing seq scans over index scans on modern hardware.
None of these changes require a restart (except shared_buffers) — apply them with ALTER SYSTEM SET and SELECT pg_reload_conf(). Always benchmark before and after with pgbench or your actual workload.